01 · The problem
Rented AI
Their models, their prices, your data on their servers.

MODEL-AS-A-SERVICE
The platform to build, govern and scale AI with confidence. Purpose-built models, trained on your data, running inside your boundary, measured against the outcome you bought.
For regulated industries that need AI to be secure, explainable and sovereign.
THE OVERVIEW, CHAPTER BY CHAPTER
A 71-second tour of the console, from the problem with rented AI to governance.
Their models, their prices, your data on their servers.
Governed at every layer, in one console.
Your own GPU and CPU servers, pooled as one fleet.
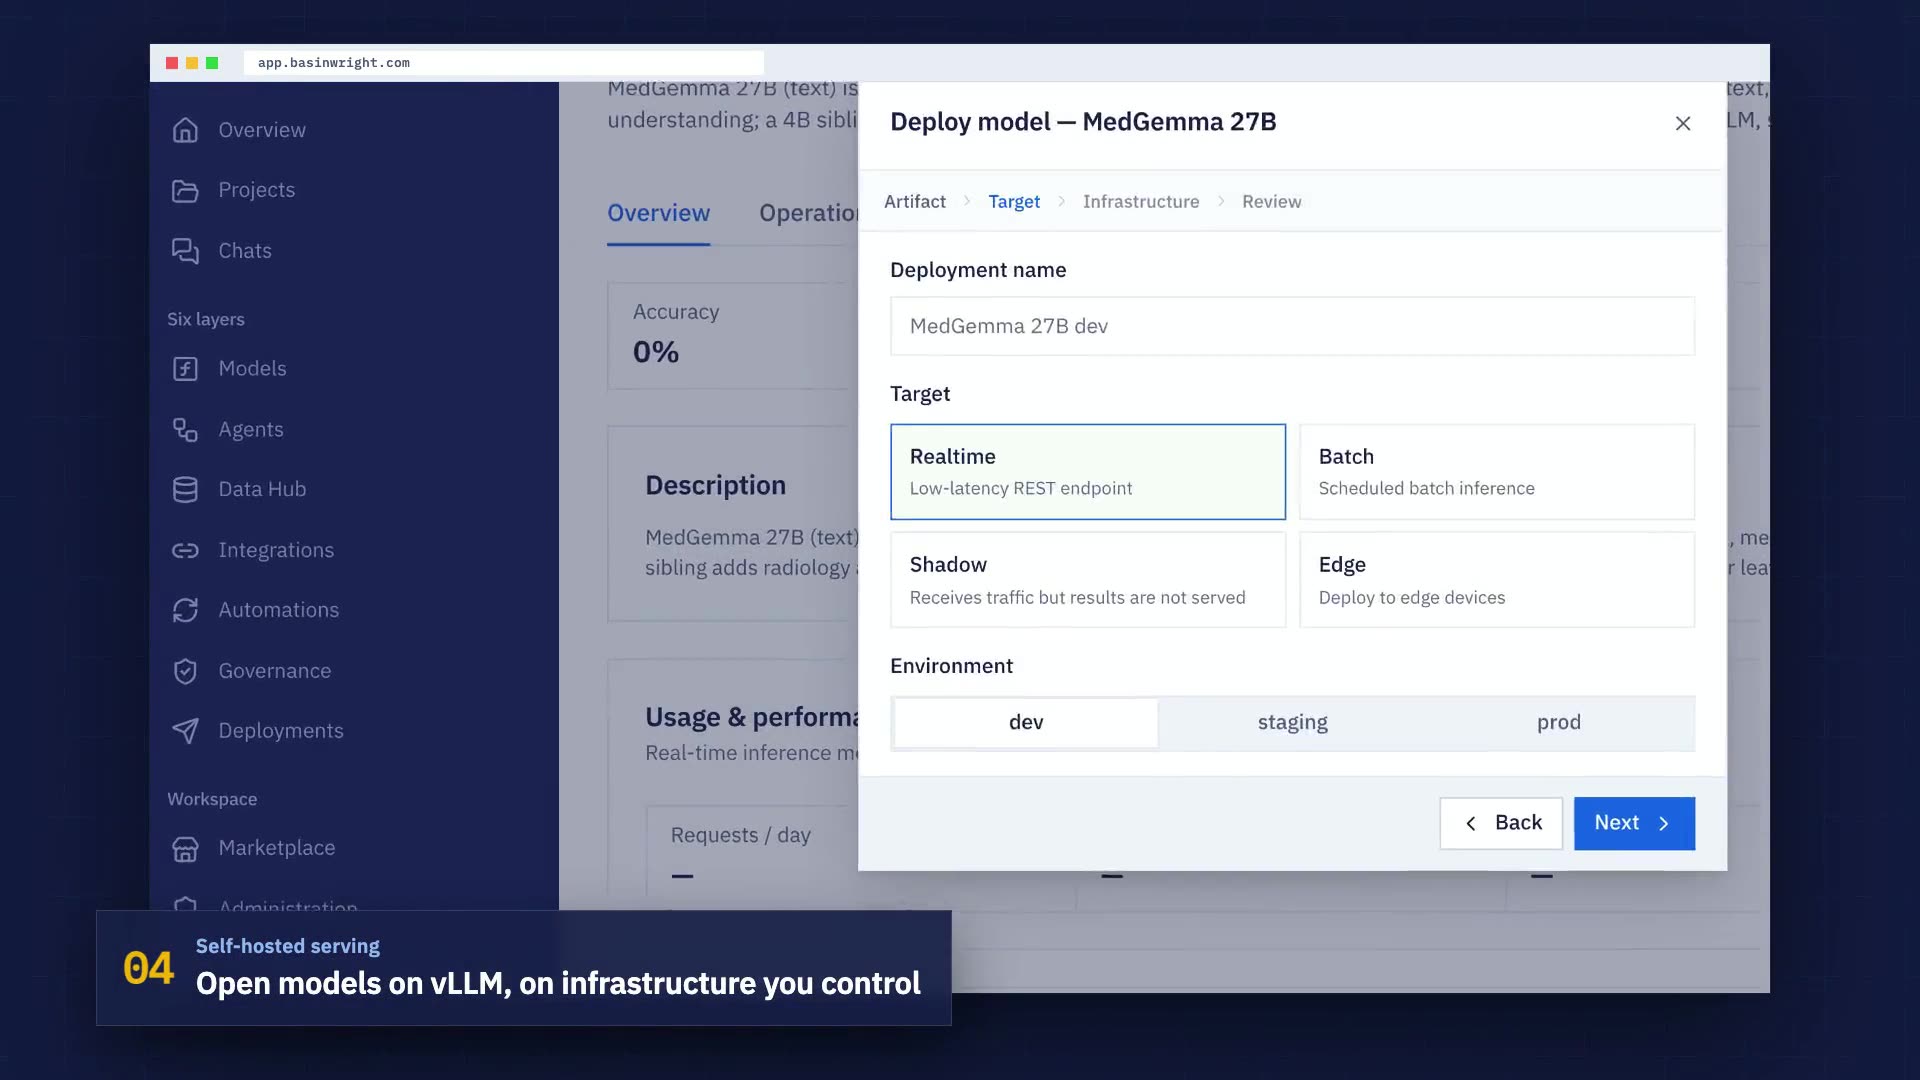
Served on infrastructure you control, to realtime, batch, shadow or edge targets.
The data that feeds every model, read where it lives.
Open-weight and custom models, and the agents built on them.
Dashboards over your own data, one project per team or business line.
Ask what is deployed, what it costs and how it is doing.
Guardrails, an audit trail and per-tenant encryption.
THE PLATFORM UNDERNEATH
The work lands in a console you operate, with your models, your data connections, your deployments and your evidence in it. Not a slide pack and a handover call.
Fraud, claims, procurement and AI safety arrive in the same place, with one audit trail and one access model behind them, rather than six vendors and six governance stories.
A REST API across the platform, Python and TypeScript SDKs, an OpenAI-compatible inference gateway that meters every call, and MCP so your models are reachable as tools.
The estate runs in your tenancy under your keys, and what it produces (models, weights, governed corpora, decision history) stays inside it.
WHAT THE PLATFORM IS MADE OF
Instead of assembling model vendors, GPU providers, a vector store, an evaluation harness and a governance story, you operate one environment, and keep it.
Deploy production-ready models without managing infrastructure.
Capacity for training and serving AI at scale, alongside CPU serving where a GPU is not needed.
Agents that plan, act and stop for a person when policy says so. 1,141 of them ship ready-made.
Meet the agents →Design, evaluate and ship AI systems without leaving one workspace.
Connect the systems your organisation already runs on and make them answerable, with citations.
Structured, semi-structured and unstructured data in one governed plane.
Trace every inference, cost centre and policy decision across the estate.
Procure vetted AI capability with commercial and compliance terms attached.
MODELS
Many vendors have reduced every problem to a prompt. That is the wrong tool for most enterprise decisions, and it is why so many pilots die in risk review. Route by cost, latency, residency or capability without rewriting application code.
Scorecards, anomaly detectors, survival and time-series models: reproducible and defensible.
Reasoning, drafting and synthesis, self-hosted and fine-tuned on your corpus.
Detection, inspection and document understanding.
Transcription, diarisation and real-time voice.
Dense and sparse retrieval tuned for your corpus.
Text, image, audio and video in a single context.
Generation, migration and review across your stack.
Clinical, legal, financial and industrial specialists.
CATALOGUE
A shipping use case arrives as a working data pipeline, a trained artifact, an evaluation report and a model card. What runs in production is calibrated on your population, your policy and your thresholds.
Real-time fraud scoring, churn risk, lifetime value and behavioural authentication.
IFRS 9 ECL, Basel IRB capital, application scorecards and transaction monitoring.
Automated underwriting, claims triage, fraud-ring detection and loss reserving.
Spend anomalies, supplier risk, three-way match, tender extraction and spend classification.
Injection, leakage, poisoning and agentic-abuse detection for your own GenAI stack.
Grounded assistants and routing over your own document estate, with citations.
On-premises embeddings, self-hosted LLM assistants and domain classifiers.
Custom models are a productised service on the same pipeline, with the same governance and monitoring.
UNDERNEATH A DEPLOYMENT
Records land unnormalised, duplicated and unlinked, from systems that never agreed on a schema. Nothing has earned meaning yet.
Entities are resolved and duplicates collapsed into one governed record. What fails the quality bar goes to quarantine, to be fixed or to expire.
Trained, tuned and evaluated on your governed data, then deployed into your tenancy and your region, under your keys.
Retrieval grounds the case in evidence, deterministic models check it against real constraints, and a language model weighs the options and explains the call.
Drift, accuracy, latency and cost per decision are monitored. A model that starts to slip is retrained and re-evaluated before it reaches a decision that matters.
Evidence builds up lane by lane and nothing is decided early. Every decision keeps the lineage of the exact records behind it, and confidence is computed, not asserted.
The model, the weights, the governed data and every decision it has made stay in your estate. No lock-in.
MODEL 360
Every model carries the same evidence, on by default: why it decided what it did, a signed trail back to its inputs, and continuous checks that it still holds.
Contributing factors and reason codes on tabular models, cited source passages on retrieval and language models. Adverse-action reason codes are native, for wherever a declined applicant has a right to an explanation.
An Ed25519-signed evidence trail linking each output to its inputs and sources, built for audit and dispute resolution rather than for a dashboard.
Drift and accuracy decay monitored statistically (PSI and CSI), output quality scored by evaluators continuously rather than once at UAT, and every inference logged and metered.
Versioned configuration and change history for every model, with validation workflows for the models that carry real risk.
SERVING
Residency, sovereignty and blast radius are usually decided before the model is. Your business data stays in your systems and is read at query time; the same platform, governance and evidence trail follow the model wherever it lands.
Scoring, forecasting and classification at a fraction of the cost. Not everything needs a GPU, and we will say so.
Embeddings, document intelligence and LLM inference on dedicated capacity.
On-premises training and inference for sovereignty and residency-constrained work.
No prompt or embedding data leaves the network. In-country residency where law or contract requires it.
CONNECTED
Route by cost, latency, residency or capability without rewriting application code.
Databases, warehouses, object stores, streams and business systems, with credentials sealed at rest.
Every option runs the same platform, with the same governance.
Anything you can click in the console, you can automate.
FOR ENGINEERS
Anything you can click, you can automate. Every call routes through the gateway, which is what makes per-team cost and drift monitoring possible in the first place.
Developer documentation →A public API across the full platform surface: projects, registry entries, deployments, guardrails and evaluators are all addressable.
Python and TypeScript SDKs, a CLI and a Terraform provider, so the estate can be managed as code rather than through a browser.
Authenticates and meters every call, so usage, cost and behaviour are visible per project, per model and per team.
Your models and data are reachable as tools by agentic clients, under the same access rules.
MODULES
Every one of these is a surface in the console and an endpoint on the API. Nothing here is on a roadmap.
Isolated workspaces with their own data, credentials, compute and members.
Register, browse, preview and query the stores your models read from.
Databases, warehouses, object stores, streams and AI providers, with credentials sealed at rest.
Version, configure and promote models, with evaluation gates before promotion.
Live endpoints with health, logs, events and rollback.
Fleet inventory, live utilisation and cost per GPU server.
Grounded answers from your own documents, with the passage attached.
Safety screening on inputs and outputs, and continuous quality scoring.
Workflows chaining models, data and actions on a schedule or trigger.
Role- and attribute-based permissions, down to the individual resource.
Per-project consumption and spend, metered at the gateway.
Every agent with its state, runs, success rate, cost and outcomes.
PRICING
The platform is priced by what you consume and what you need governed. A delivered use case is scoped separately, against its outcome, because that is work with a target attached, not a seat licence.
Everything you need to prototype against frontier models.
Talk to sales →Dedicated capacity and the controls a real product needs.
Book a session →Private networking, governance and procurement-grade terms.
Talk to sales →National-scale compute with full data and operational sovereignty.
Talk to sales →Separately from the platform, and deliberately so. We agree the target metric up front and it becomes the definition of done. We tell you plainly whether the use case ships today as a reference implementation to be tuned on your data, or is built to order. A shipping use case typically goes from kickoff to a governed, monitored endpoint in weeks, and drift monitoring and retuning after go-live are part of the engagement.
No. Compute is consumed rather than reserved unless you want committed capacity. CPU serving covers a large share of deterministic use cases at a fraction of the cost, and we will tell you when a use case does not need a GPU.
You keep them. The model, the weights, the governed data it learned from and its decisions are inside your estate throughout. Exit terms are agreed up front rather than negotiated under pressure later.
Yes. The platform is a subscription with consumption on top; a delivered use case is scoped against its outcome.
We describe our controls plainly and do not claim certifications we do not hold. Ask for the current assurance position and you will get the real answer, including where it is incomplete. See Security & governance.